

 +972 52-548-6969


In my last post on the topic, I talked about ImmutableDictionary and why it was too costly for us to use. At the same time, it is basically the data structure that we need for the task at hand. That task is keeping track of the current set of modified pages, with multiple concurrent versions running at the same time.
ImmutableDictionary is perfect for the task, because it gives us the right immutable behavior, but its performance makes it unacceptable. So the solution is to design a data structure that would fit our needs and requirements.
The people who wrote ImmutableDictionary are not stupid. They didn’t set out to make something that would be slow. The issue is that they set out to solve a generic problem. We can benefit from specializing the data structure for our needs (removing a lot of complexity along the way).
Concretely, we need something that:
- Provides O(1) lookup.
- Plays nicely with the GC and allocates rarely.
- Has a simple structure for the GC to work with (not a lot of interior pointers).
- Still supports the snapshot model that made the immutable dictionary so attractive: the ability to discard values while old snapshots remain valid and consistent.
The problem is combining all of those together. It is much easier if we can drop any of those requirements.
I started the design by dropping the very notion that this is a generic data structure. It isn’t an ImmutableDictionary<TKey, TValue>; instead, we have the ScratchPagesTable data structure.
Conceptually, this is similar to a Dictionary<long, ScratchEntry> in terms of how we’ll use it. ScratchPagesTable is essentially an open-addressing hash table, using linear probing and Fibonacci hashing. That is pretty basic, to be honest. That isn’t what makes it interesting.
Here is the actual layout of the data structure:
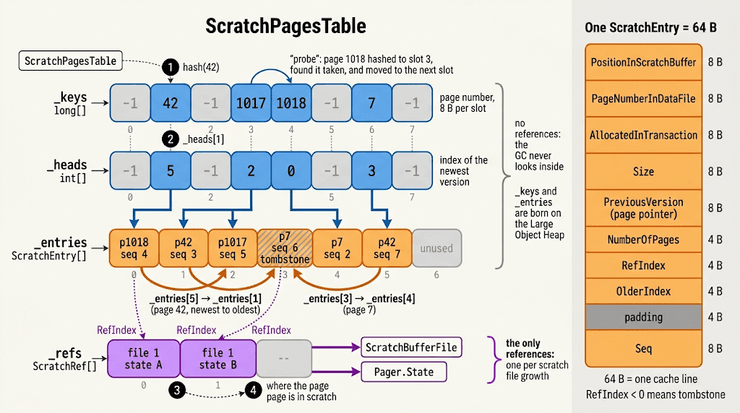
The entire design for this table is meant to make it easier for the GC to work. Note that the first three arrays here are plain objects. The _keys and _heads are parallel arrays, which we use to find the actual entry in the _entries array.
The _entries array contains the ScratchEntry structs, which you can see on the right side. Each struct contains all the details about the current entry. Note that the entry also does not use any pointers.
The only pointers in the entire ScratchPagesTable are in the _refs array. Each ScratchEntry in the table points to a location in a particular file. Instead of carrying a pointer in each of the (many) entries in the table, we put them all in the _refs array and refer to them by index from the entries.
We may have tens to hundreds of thousands of entries in the table, but we’ll usually have a much smaller number of files (almost always under ten). By centralizing the references in a single small array, we made the job of the GC so much simpler.
When it needs to scan the ScratchPagesTable to see what is used, it can mark each of the top three arrays immediately and not walk their contents (because they have no pointers). And the _refs array is very small, so that isn’t meaningful.
Let’s talk about the concurrency aspect here. We have the ability to take cheap snapshots from this data structure, which gives us a stable view of the data.
We take advantage of the fact that we have a single writer, so there is just a single thread that mutates the table. Then that same thread is the one that is publishing the new snapshots to other threads.
Here is what this looks like:
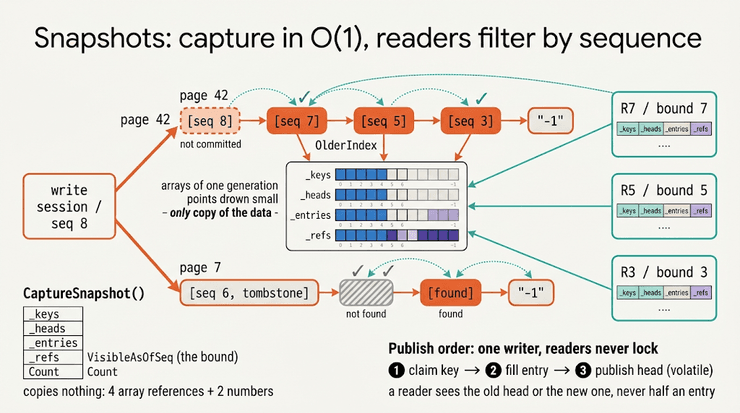
A snapshot simply captures references to all four arrays, the total count of items in the table, and, most importantly, the sequence number that was stamped on the snapshot when it was created.
If you look at the ScratchEntry layout, you’ll note that we have the OlderIndex field and the Seq field. Together, those represent a linked list that we can scan to find the first entry (value or tombstone) whose sequence number is less than or equal to the current sequence number that we are using.
A reader using a snapshot holds a mutable array, but the use of the sequence number ensures that it can never actually observe changes that happened after the snapshot was taken.
We don’t need to worry about concurrent mutation, since this is meant to be used with a single publisher (already guaranteed by the way RavenDB works).
Of course, if we just keep on using the table in this manner, we’ll have to deal with garbage. How do we get rid of old entries that no snapshot looks at? Don’t we have to replace the GC ourselves?
Let’s go back to the concept of the sequence. RavenDB keeps track of all the active transactions, and each of those holds a snapshot. That means that we have a cheap way of getting the oldest snapshot and its sequence.
Whenever we create a new write transaction, we check what the oldest sequence number is. That means that when we update the scratch table, we can prune the chains when we find entries that no one is able to look at any longer.
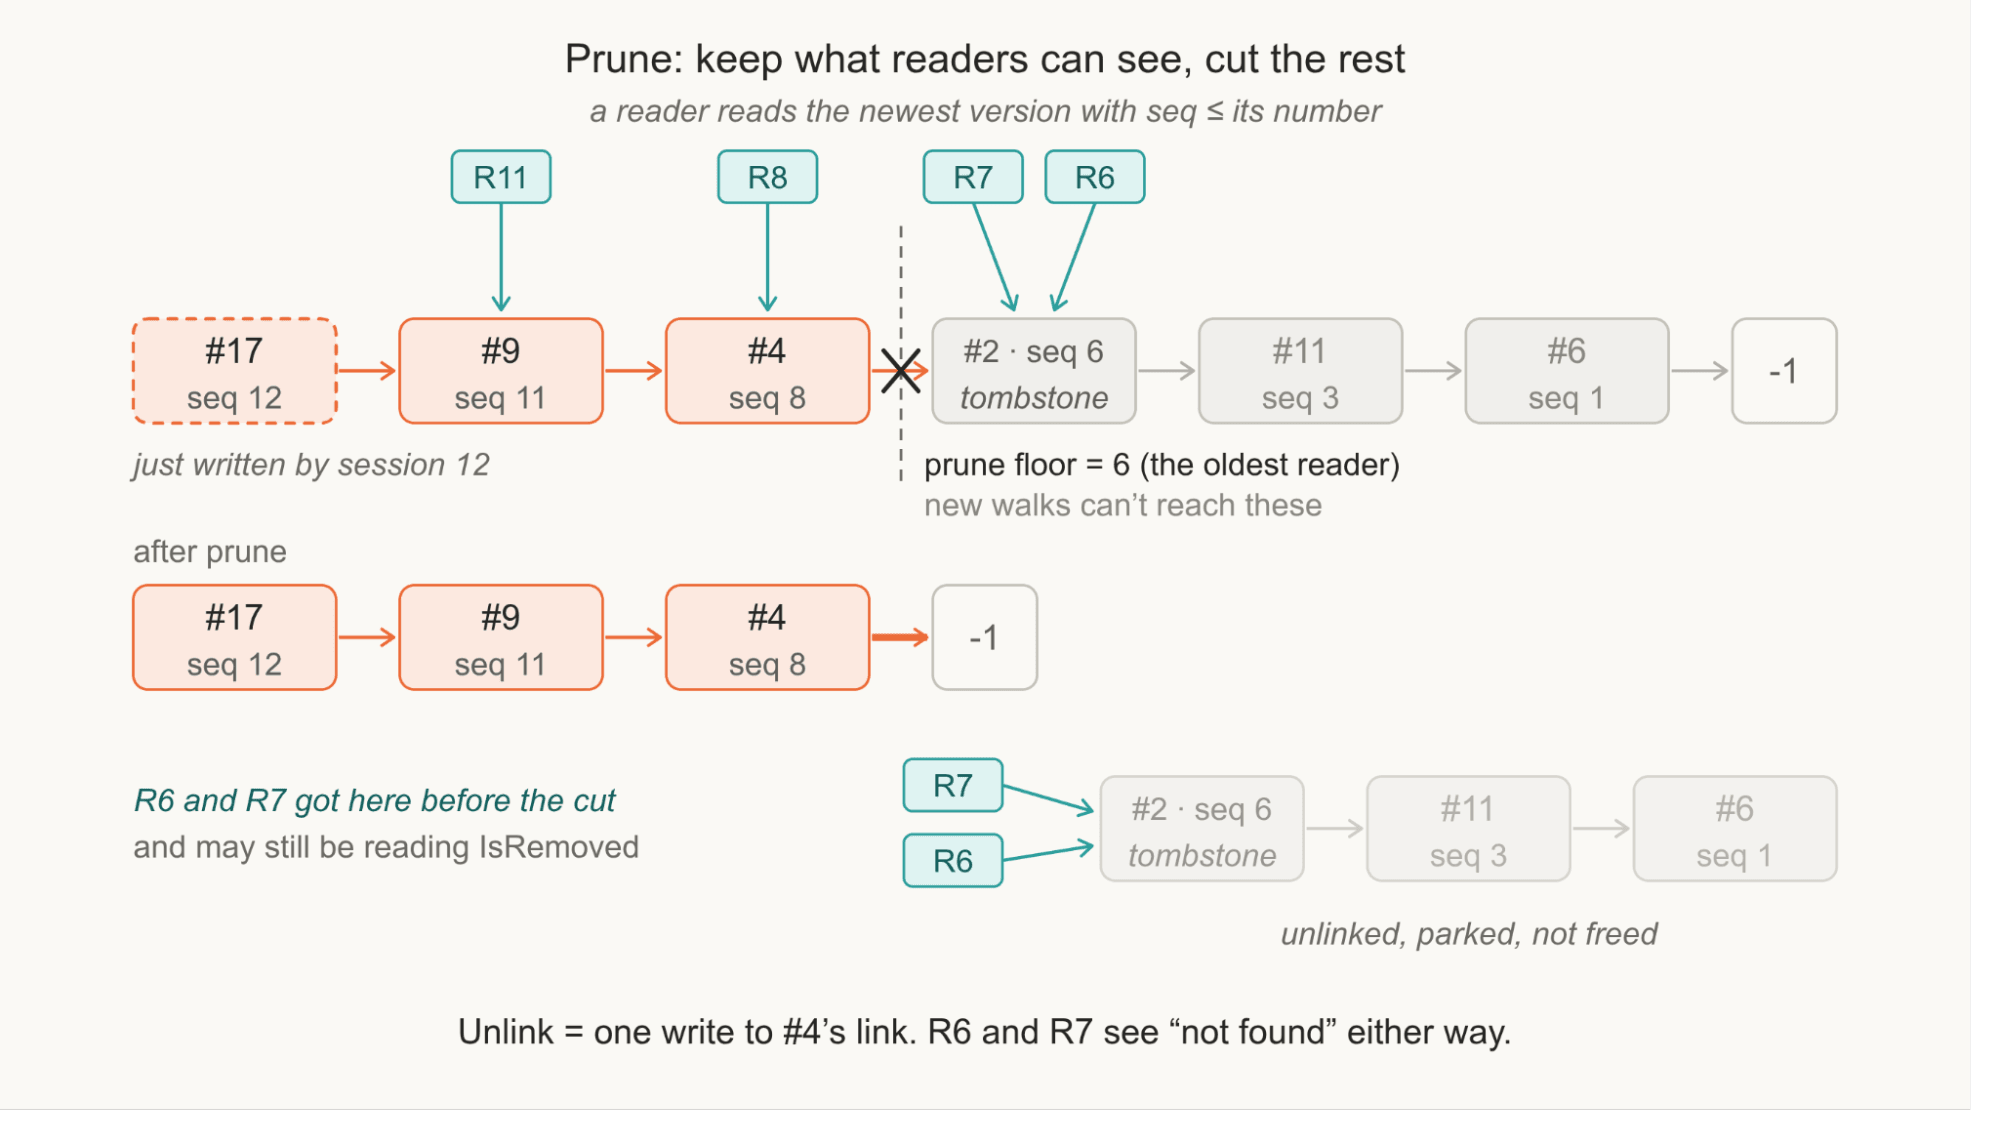
Pruning the chain in this manner doesn’t mean that we can immediately use the entries we unlinked. The issue is that a reader may want to read them. Let’s assume we have a deletion, like in the diagram above. When we prune, we cannot just immediately reuse the entries, because the readers may have already started looking at them.
What we do instead is park them, as you can see in the following diagram:
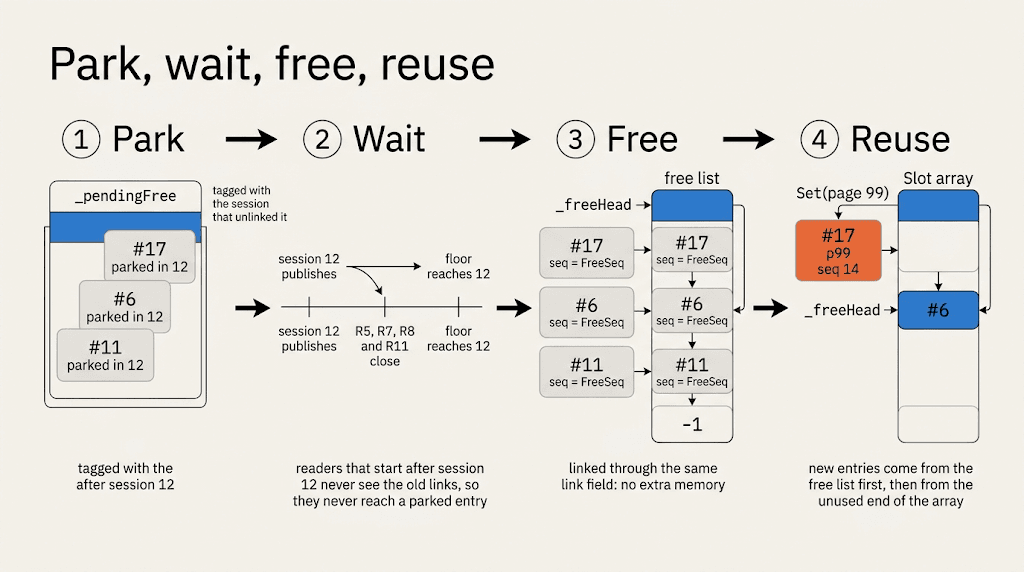
Once we have progressed through enough transactions and all currently opened transactions started after the entries were parked, we can reuse those entries. Of course, if we have enough entries, we may need to allocate brand new arrays (re-hashing). That is safe to do because all the old snapshots contain the old references; we just discard them.
This model of pruning the old versions from the end is great for most scenarios. However, there is a particularly nasty use case where it utterly breaks down. What happens when we have a long-running transaction? We have to keep all the versions alive until the oldest read transaction is done with them.
As it turns out, there is a very common scenario where this can happen. If we run a backup, we may hold a read transaction for a long time. Write transactions while the backup is running will cause the chain to become longer and longer. The design of the scratch table means that we keep things fast for the current transactions and recent ones.
The old transaction has to traverse the entire chain each time, becoming slower the more time goes by. The slower it becomes, the more time it takes, the more write transactions can happen, the slower it becomes… That isn’t a fun scenario.
RavenDB handles this scenario explicitly. When we detect that the chain is too deep, we start pruning the chain. We discard all the intermediate transactional versions that exist between the current committed version and the oldest read transaction.
You can see what this looks like in the following diagram:
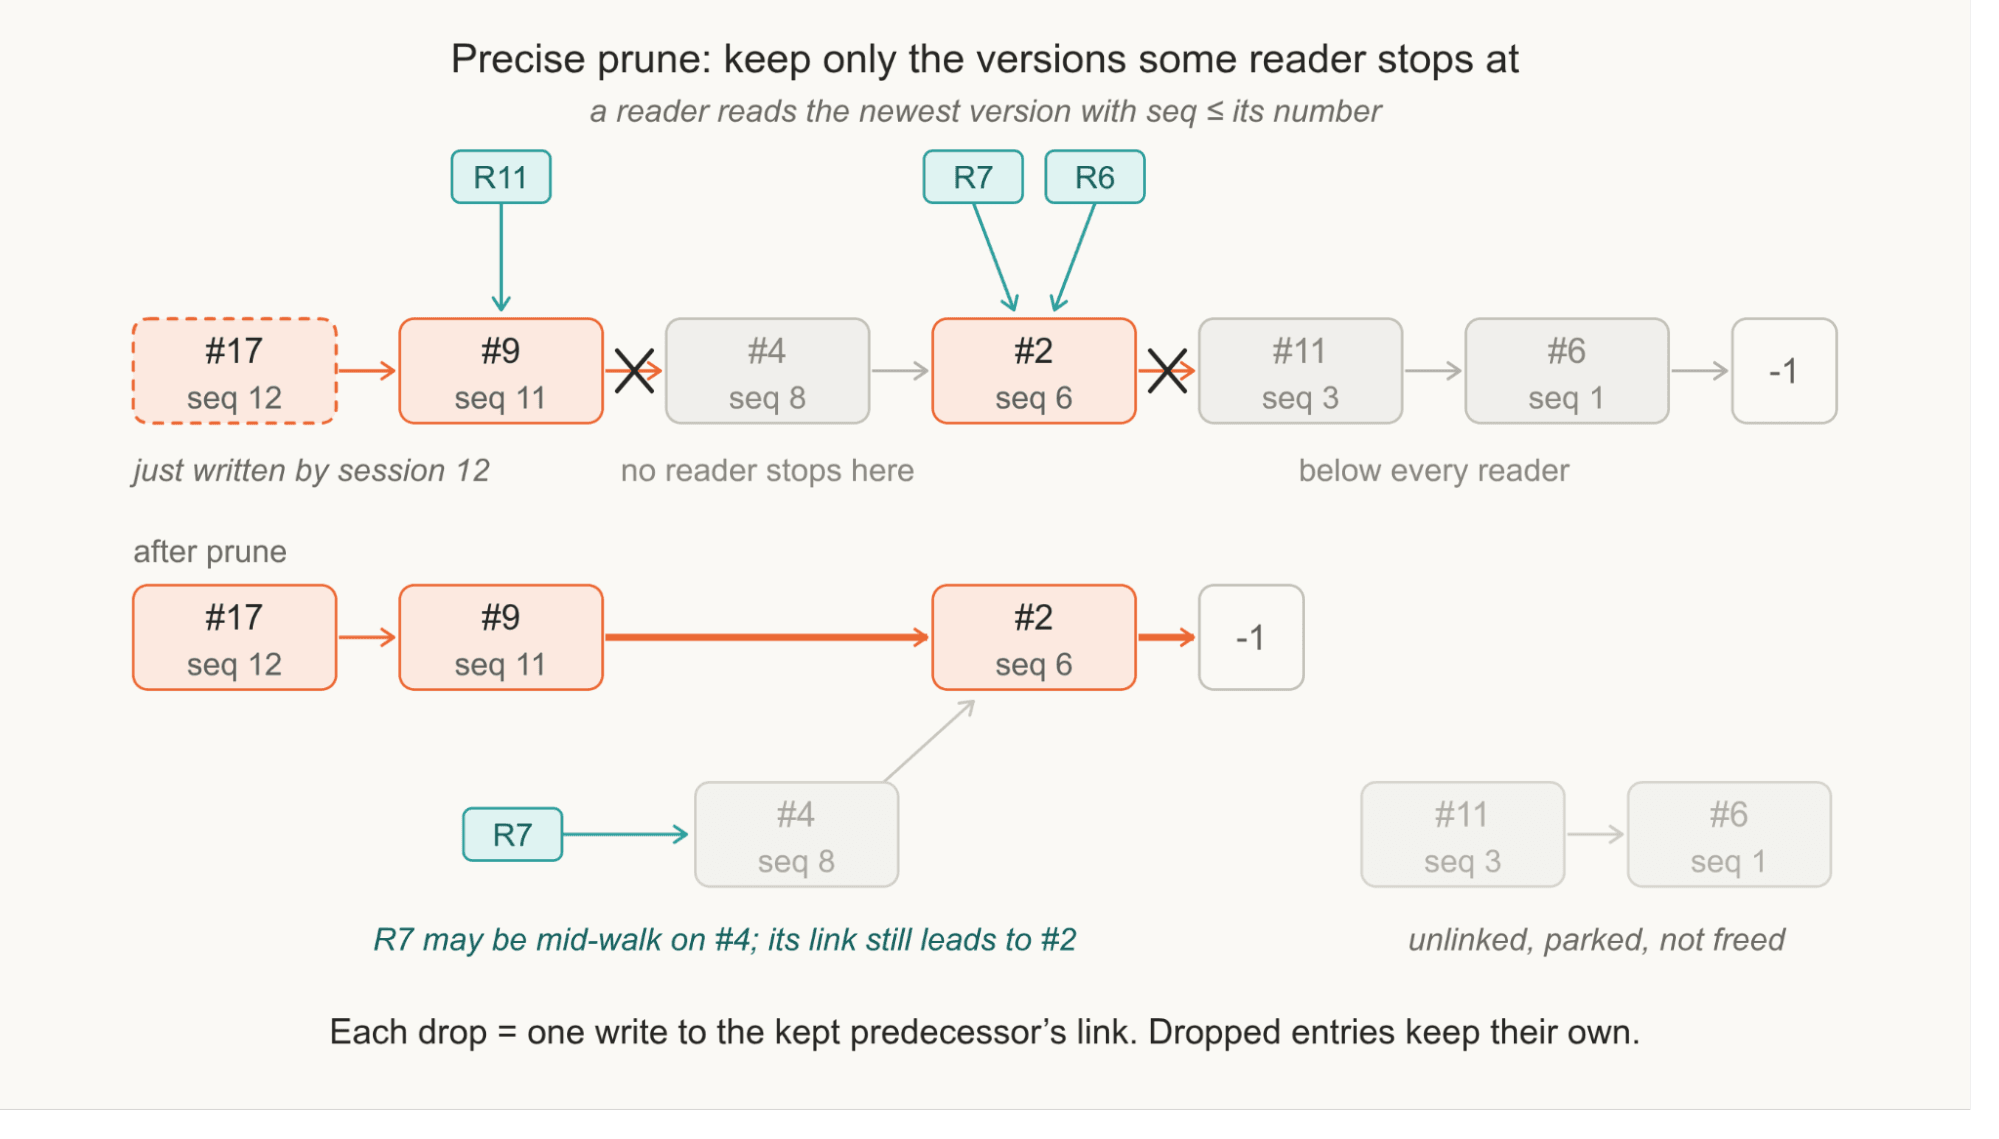
Using this mechanism, we can keep the amount of work that old transactions need to do under control.
The end result of all of this work is a high-performance concurrent data structure that takes into account both how it is actually being used and the internal intricacies of the .NET garbage collection. It isn’t your run-of-the-mill data structure, nothing that would be relevant off the shelf.
It is also directly responsible for an improvement of over 20% in the performance of RavenDB when we compare the two versions side by side.